What server maintenance should include
Planned patching, backups with test restores, alerts, access, renewals and reporting: how to tell whether your server is being properly looked after.
By Víctor Piles TemporalSRE and systems engineerPublished on Updated on 6 min read
“We have maintenance” can mean very different things. For some it means someone restarts the server when it fails; for others, weekly updates, verified backups and alerts. If you pay for server maintenance, or are thinking of doing so, this list will help you know what you should be getting and what to ask.
In short: proper maintenance includes planned security updates, backups with test restores, monitoring with alerts, review of access and logs, renewal of certificates and licences, and up-to-date documentation. It should leave a trail: a regular report saying what has been done and what risks remain.
Preventive maintenance versus firefighting
The “call me when it breaks” model looks cheap until something breaks. An unpatched server piles up known vulnerabilities, a disk that keeps filling up ends up stopping the database, and an expired certificate takes the website down on a Sunday. Preventive maintenance means doing small tasks often so those surprises never arrive.
The tasks that can’t be missing
System and application updates
Security patches for the operating system (Linux or Windows Server), for the software running on top of it (database, web server, control panel, hypervisor) and for the firmware when the manufacturer releases fixes. The sensible approach is to:
- Apply security patches at a fixed, agreed frequency.
- Do it in an agreed window, with a backup taken first.
- Test first in a staging environment when the change is a big one, such as a major version of the operating system.
Backups that get checked
It isn’t enough for the backup to “run”. You have to check that it finishes without errors, that there’s a copy outside the building and that it can be restored. A regular test restore is the only way to know. I explain it in detail in the guide on 3-2-1 and immutable backups.
Monitoring and alerting
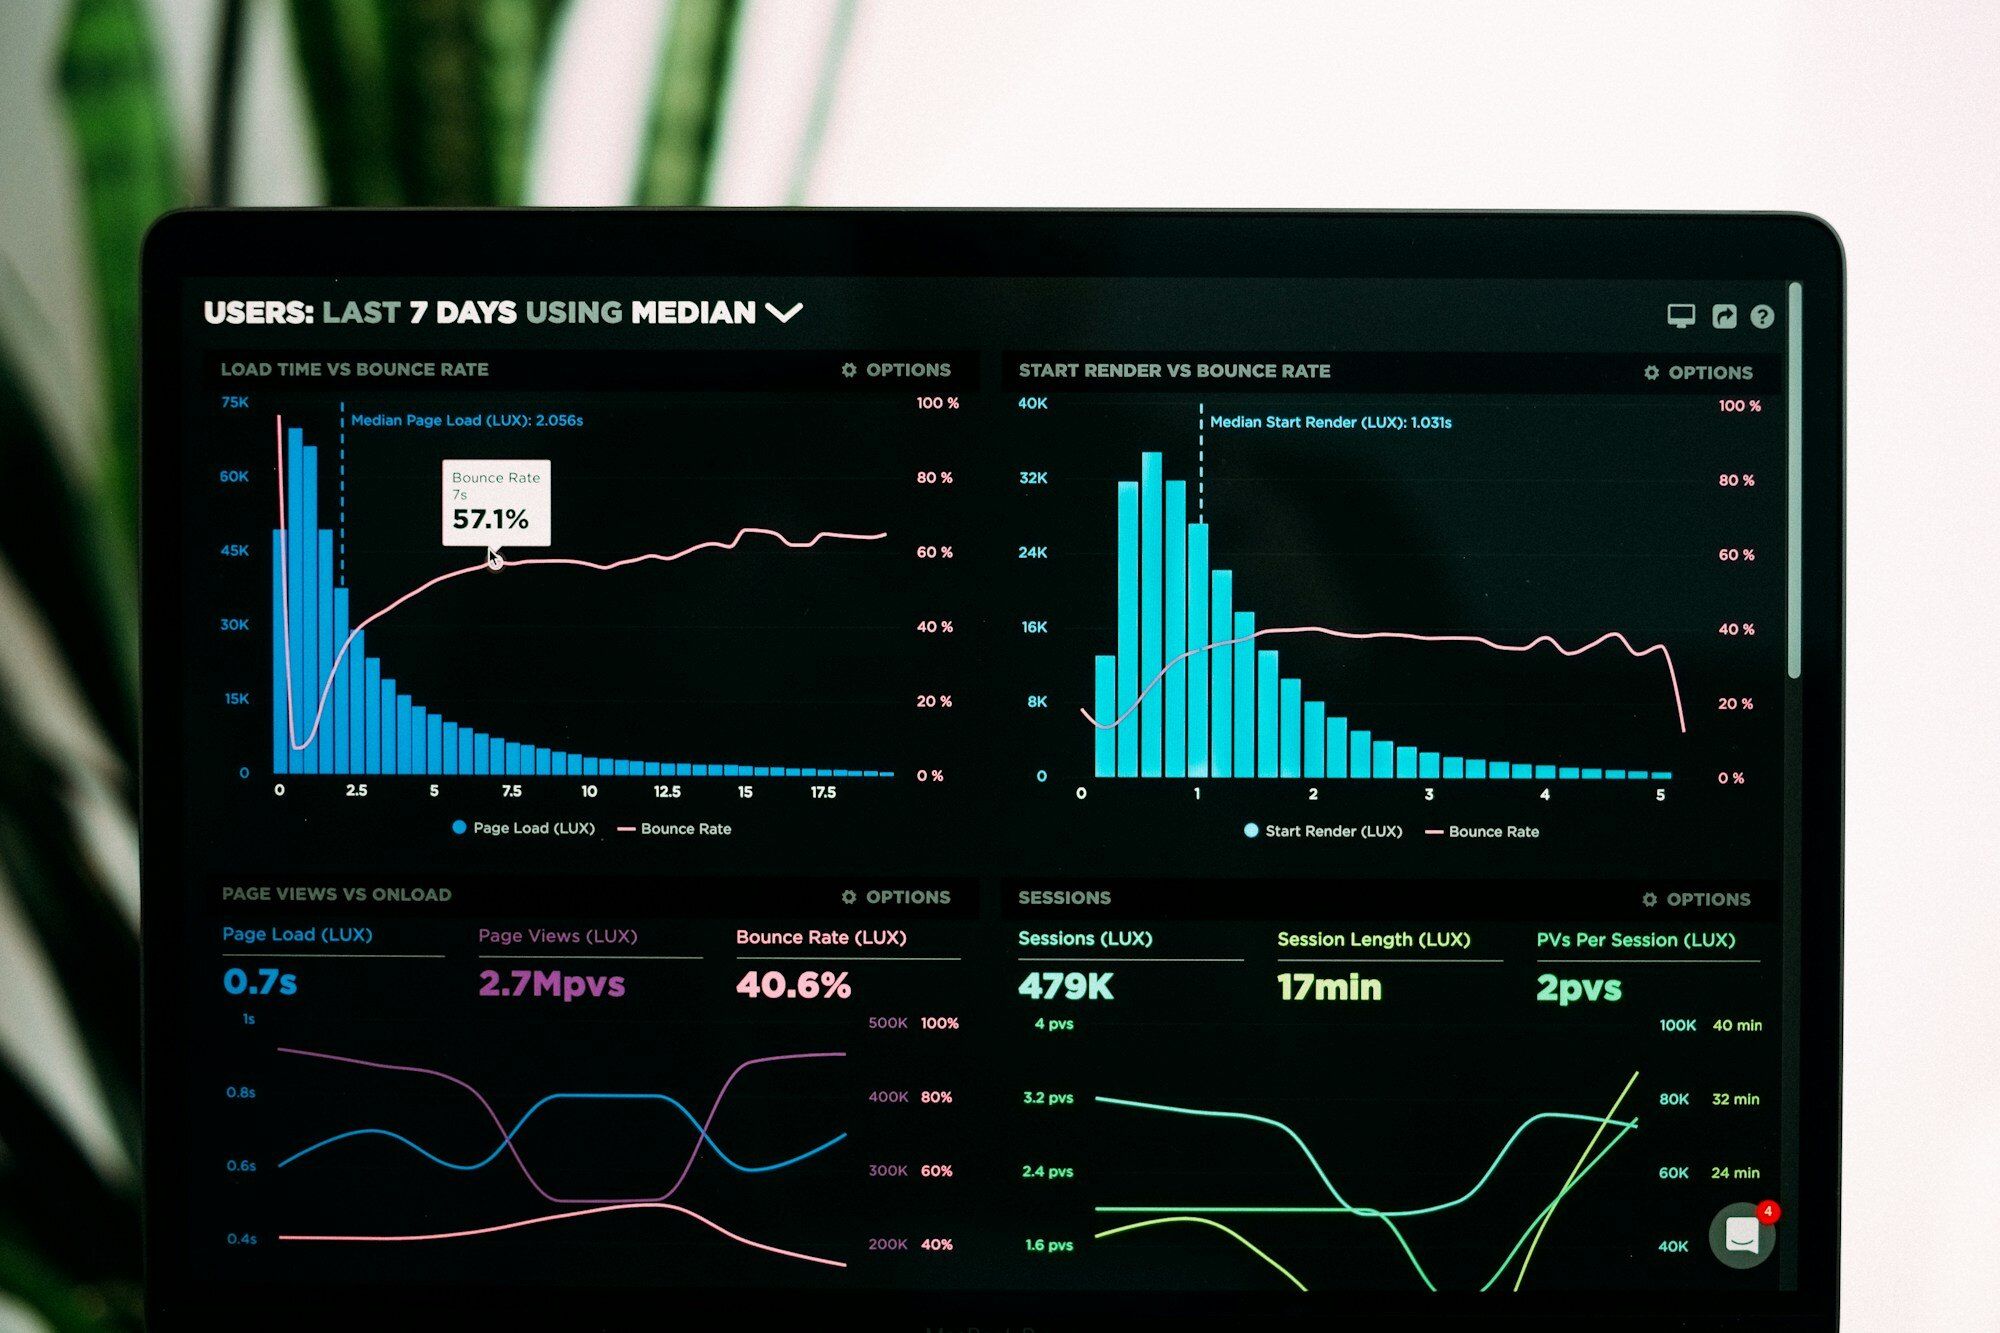
A system that watches disk, memory, CPU, services that are down, disk health (SMART or RAID) and certificate expiry, and that warns you before the problem affects users. Tools such as Zabbix, Prometheus with Grafana or Uptime Kuma do this well; the tool matters less than the fact that someone looks at the alerts.
Security and access
- Review who has access and remove the accounts of people who have left.
- Administrative access only through a VPN or with an SSH key, never with a password exposed to the internet.
- A firewall with only the essential ports open.
- Review the logs for access attempts and repeated errors.
Renewals and expiry dates
TLS certificates, domains, licences, hardware warranties and the end of support for the operating system. A calendar of expiry dates avoids nasty surprises and lets you plan migrations in good time.
Documentation
What services there are, how to access them, where the backups are, how to restore and who to call. If the engineer changes, the documentation is what saves you from starting from scratch.
| Task | Indicative frequency |
|---|---|
| Review alerts and backup status | Continuous or daily (automated) |
| Security patches | Planned, at a fixed frequency; urgent ones as soon as they’re released if critical |
| Test restore | Regular, at least of the most important data |
| Review of users and access | Regular, and whenever someone joins or leaves |
| Review of expiry dates (certificates, domains, licences) | Monthly |
| Documentation updates | With every change |
| Report to the client | Regular (monthly or quarterly) |
The exact frequency depends on how critical the server is and how often it changes; what matters is that it’s agreed in writing.
As CTO of an online platform, 99.9% availability was sustained through automated processes and testing on every change. A standalone server is a different scale, but the idea still applies: automate what’s repetitive and check every change.
What to ask before signing a maintenance contract
- Which tasks exactly are included, and how often? Ask for the list in writing.
- What’s the response time? And during which hours. Distinguish between automated monitoring, which can run around the clock, and the human response. In my case, I respond during business hours, within a timeframe agreed according to severity.
- How is the server accessed? With named accounts and over a secure channel.
- Will I get a report? Without a report, you don’t know whether the work is being done.
- Who owns the credentials and the documentation? It should be your company.
- What happens if we stop working together? There should be an orderly handover.
Linux, Windows Server and container-based servers
Maintenance is similar in all three cases, with some nuances. On Windows Server, monthly updates and Active Directory carry more weight; on Linux, package updates and service configuration; and when applications run in Docker containers, updating is usually safer because you swap the image and can roll back if something fails.
On the SRE as a service page I describe how I do it each month. In examples you can see what a monthly report looks like. Would you like me to review your server? Book a free 20-minute call.
Frequently asked questions
How do you access a server to maintain it?
Almost always over a VPN. Updates, backups, monitoring and configuration changes are all done through it.
How often should a server be restarted?
There’s no fixed figure: you restart it when an update requires it (for example, a kernel patch on Linux or the monthly update on Windows). What matters is doing it in a planned window and checking afterwards that all services have come back up.
What happens when the operating system reaches end of support?
It stops receiving security patches and becomes riskier every month. You need to plan the migration to a supported version in good time, ideally months before the end-of-support date.
Does maintenance include backups?
It should include at least monitoring them and running test restores. The backup system itself can be part of the same service or come within a service such as SRE as a service.
References
- INCIBE: Decálogo de ciberseguridad para empresas: access control, backups with restore tests, updates and continuity (in Spanish).
- Microsoft Learn: product lifecycle, to look up end-of-support dates for Windows Server.